GPU Innovation Roadmap: What's Leading the Market in 2024—Architecture, Performance, and Supply Chains
Explore GPU technology trends 2024: architectural advances, performance benchmarks, energy efficiency, and supply chain dynamics shaping corporate procurement decisions.
The New GPU Landscape
The GPU market in 2024 looks nothing like it did five years ago. What began as hardware for rendering graphics has become the backbone of AI training, data analytics, and scientific computing. Corporate demand for GPUs has shifted from niche applications to mission-critical infrastructure, and the stakes have never been higher.
Understanding GPU technology trends 2024 innovation performance means looking beyond marketing claims. It requires examining actual architectural changes, measurable efficiency gains, and the geopolitical forces shaping supply. This analysis draws on public data and industry observations to help you navigate a market defined by scarcity, competition, and rapid technical evolution.
Disclaimer: This content reflects market analysis and publicly available information. It does not constitute investment advice, purchasing recommendations, or endorsements of specific products or manufacturers.
Architectural Shifts Driving 2024 Performance
Modern GPU architectures have moved decisively toward parallelism optimized for matrix operations. The fundamental design of graphics processing units now prioritizes tensor cores and specialized blocks that accelerate neural network workloads. Traditional rasterization pipelines remain, but they share die space with compute-focused logic that didn't exist a decade ago.
Memory bandwidth has become the primary bottleneck. High-bandwidth memory interfaces and on-chip caches determine whether a GPU can keep its thousands of processing units fed with data. Designs that integrate memory closer to compute logic show measurable advantages in AI inference and large-batch training tasks.
Chiplet-based designs are emerging as a manufacturing strategy. By splitting monolithic dies into smaller tiles connected via high-speed interconnects, manufacturers improve yield and mix different process nodes on the same package. This approach offers potential advantages in cost and supply management compared to single-die methods.
Energy Efficiency and Data Center Reality
Power consumption defines GPU viability in enterprise environments. A card that delivers 20% more throughput but consumes 40% more power often loses to more efficient alternatives when calculating total cost of ownership. Data centers measure performance per watt, not peak FLOPS.
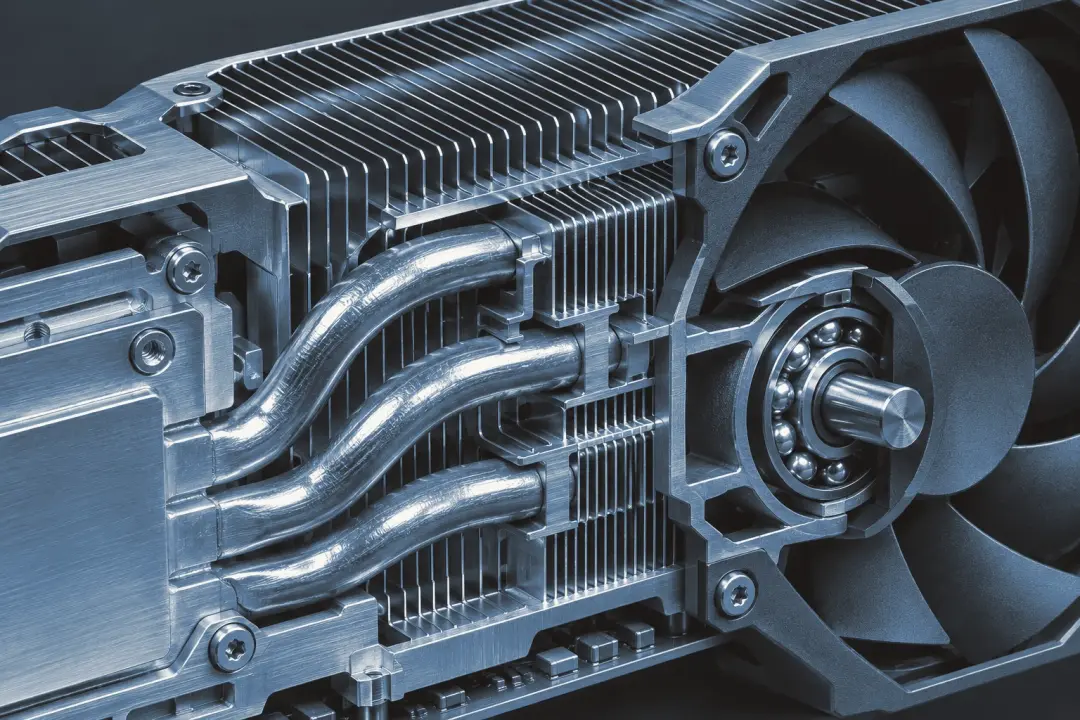
Thermal design matters as much as silicon efficiency. Cards that require exotic cooling solutions or exceed standard rack power budgets create deployment friction. The most adopted enterprise GPUs balance raw compute with realistic thermal envelopes that fit existing infrastructure.
Efficiency gains in 2024 come primarily from process node improvements and better power gating. Moving from 7nm to 5nm or 4nm fabrication reduces leakage current and allows higher clock speeds at the same power draw. Dynamic voltage and frequency scaling has become more granular, letting idle processing blocks shed power without waiting for global state changes.
Market Dynamics and Manufacturer Competition
The GPU market in 2024 remains concentrated among a small number of manufacturers, each competing on different dimensions. One focuses on software ecosystem lock-in through proprietary development tools. Another emphasizes open standards and compatibility with existing HPC infrastructure. A third targets cost-sensitive segments with competitive performance-per-dollar ratios.
Competition drives innovation, but it also creates fragmentation. Different manufacturers support different precision formats, memory types, and interconnect standards. This makes vendor switching costly and locks enterprises into multi-year technology stacks. The broader semiconductor industry faces similar standardization challenges across all chip categories.
Supply chain resilience has become a competitive factor. Manufacturers with diversified fab partnerships and flexible packaging options weathered recent shortages better than those dependent on single suppliers. Geopolitical tensions between major economies continue to influence where chips are designed, fabricated, and assembled.
Practical Selection Criteria for Enterprise Deployment
Choosing GPUs for specific applications requires matching workload characteristics to hardware capabilities. Inference workloads favor low-latency designs with efficient int8 or fp16 execution. Training large models demands maximum memory capacity and bandwidth, even if that means higher power draw. Simulation and rendering still benefit from traditional graphics pipelines.
Software compatibility often matters more than raw specs. A GPU that delivers 30% better theoretical performance but requires rewriting existing codebases rarely justifies the migration cost. Evaluate driver stability, framework support, and whether your current tools can utilize new hardware features without major refactoring.
Consider the full system context. PCIe generation, CPU bottlenecks, network bandwidth, and storage speed all constrain GPU utilization. A deployment that maxes out interconnect before saturating compute wastes money on underutilized silicon. Balanced systems outperform unbalanced ones regardless of individual component specs.
Looking Ahead: Supply, Demand, and Market Forces
GPU scarcity persists in segments with the highest demand. AI's impact on video memory requirements continues to outpace manufacturing capacity expansion. Lead times for high-end datacenter cards stretch months, and spot market prices reflect the supply-demand imbalance.
Regulatory factors will shape access. Export controls and technology transfer restrictions already limit which GPUs can ship to certain jurisdictions. Government policies around semiconductor manufacturing influence where future capacity gets built and who can access it.
The market will continue fragmenting by use case. General-purpose GPUs that try to serve all workloads adequately will coexist with specialized accelerators optimized for narrow tasks. Enterprises will increasingly deploy heterogeneous compute fleets rather than standardizing on a single architecture. Understanding these GPU technology trends 2024 innovation performance dynamics helps organizations plan procurement that aligns with both current needs and future flexibility.
Common Questions About GPU Market Trends
What makes a GPU suitable for AI workloads versus traditional graphics rendering?
AI workloads prioritize high-throughput matrix multiplication and large memory bandwidth for moving training data. They benefit from tensor cores, high-capacity HBM, and efficient fp16 or int8 precision. Graphics rendering still relies on traditional rasterization pipelines, texture units, and geometry processing that AI cards often deprioritize to save die space for compute logic.
How do export restrictions affect GPU availability in different markets?
Export controls limit which high-performance GPUs can ship to certain countries, particularly those with advanced AI capabilities. Manufacturers sometimes create region-specific variants with reduced specs to comply with regulations. This creates market segmentation where equivalent hardware costs more or remains unavailable depending on the buyer's location and end-use declaration.
Should enterprises wait for next-generation GPUs or buy current hardware?
The decision depends on deployment timeline and workload urgency. If current GPUs meet performance requirements and are available with acceptable lead times, delaying for future hardware risks opportunity cost. Next-generation cards will offer improvements, but they'll also face launch supply constraints and early-adopter driver instability. Balance immediate needs against the cost of waiting.
What role does software ecosystem maturity play in GPU selection?
Software support often determines real-world usability more than hardware specs. A GPU with excellent paper performance but immature drivers, limited framework support, or poor debugging tools creates friction that slows development. Evaluate whether your existing codebase, libraries, and team expertise align with the hardware you're considering before committing to a platform.